ICC-NO consists of 438 spoken and written texts amounting to ca. 880 000 running words in total.
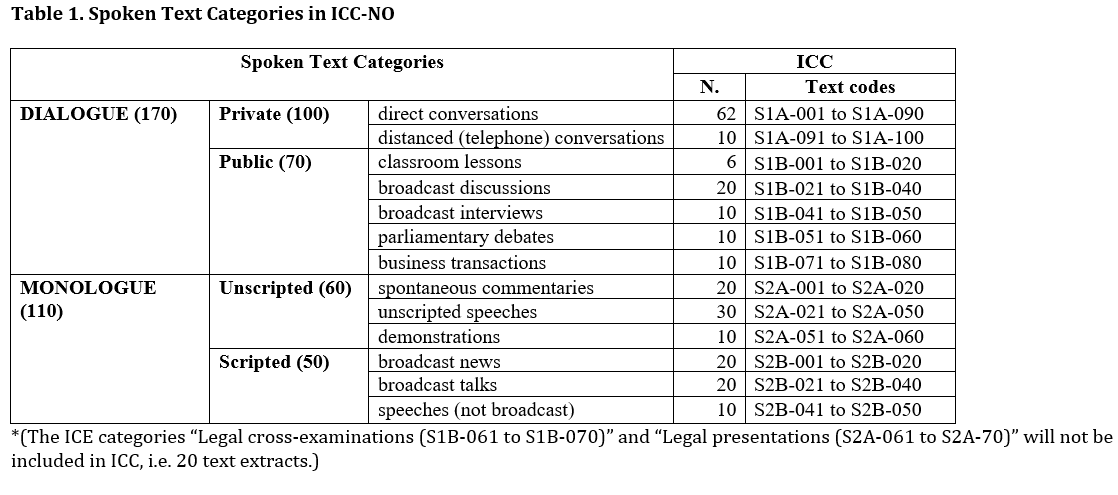
The spoken part of ICC-NO contains 238 2,000-word texts/extracts of transcribed material, distributed across various text categories. The spoken part of ICC-NO thus amounts to roughly 480,000 running words. Originally, and following the ICE design, the aim was 280 files (560,000 words). However, the categories "Direct conversations" and "Classroom lessons" proved difficult to complete. Table 1 gives an overview of the distribution of texts in each category.
The sound files were transcribed manually in Elan. Following advancements in automated trancription, different systems were tested, but the variable quality and the fact that the earliest files collected in the project had been transcribed in Elan, made us opt for Elan transcribed files only. (But read the Blog on automated transcription (... og så har vi automatisk transkripsjon – hvordan står det til der? Status høsten 2023), written by research assistants Hedda Roska and Camilla Sætehaug.)
The Elan transcriptions were converted into XML/TEI using EXMARaLDA (through the Partitur Editor) (www.exmaralda.org; Schmidt T and Wörner K (2014), “EXMARaLDA”, In Handbook on Corpus Phonology, pp. 402-419. Oxford University Press).
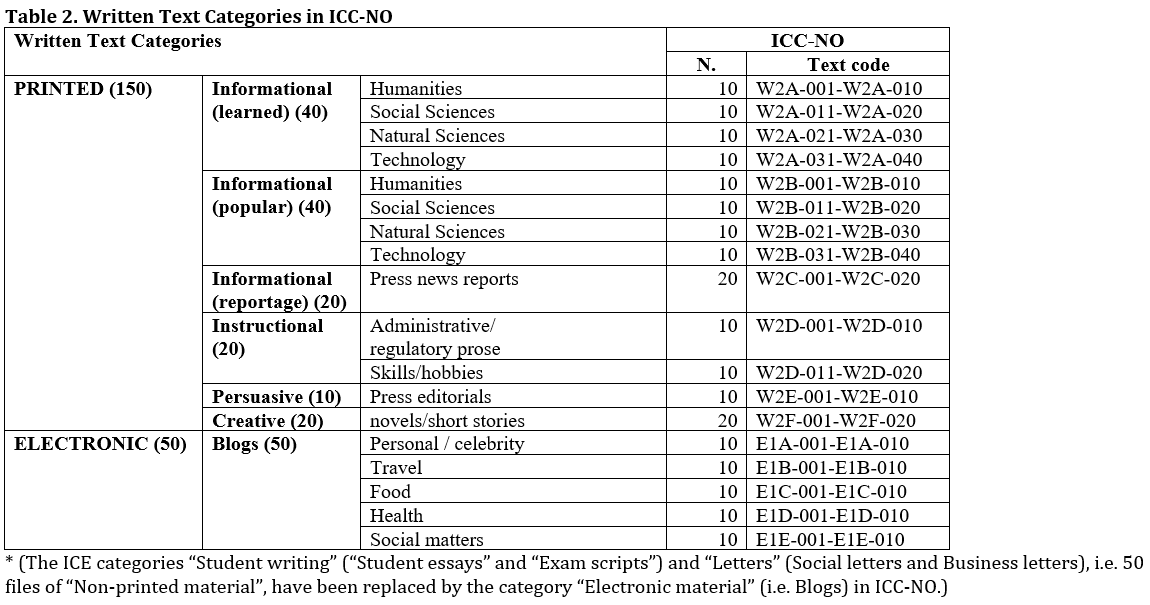
The written part of ICC-NO contains 200 2,000-word texts/extracts distributed across various text categories. The 200 texts constitute the full written part of ICC-NO (ca. 400,000 words). Table 2 gives an overview of the distribution of texts in each text category.