Nettsider med emneord «Glossa»
Eit korpus med digitale sosiale meldingar frå ungdommar på niande trinn på fire skular.

Speech corpus where Americans of Norwegian and Swedish heritage speak their heritage language
The Corpus of Doctor-Patient Consultations from Ahus is a unique corpus of transcribed dialogue in Norwegian between doctors and patients in different types of consultations at Akershus University Hospital (Ahus).
Eight small Ethiopian speech corpora are available to everyone in the search tool Glossa: Amharic, Gumer, Hadiyya, Hamar, Kambaata, Muher, Oromo, and Tigrinya.
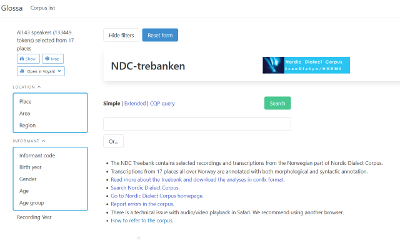
Glossa offers a modern, simple and functional search interface with advanced results management for both written corpora, multilingual corpora and speech corpora.

Icelandic youth language - Íslenskt unglingamál is a speech corpus with group conversations containing nearly 200 000 tokens.
LBK is a representative, weighted corpus made for lexicographic purposes with Bokmål texts from 1985 - 2013.

LIA Norwegian comprises 3.5 million words from historical dialect recordings, elicited from 1382 informants from 227 local areas in Norway.

LIA Sápmi - Sámegiela hállangiellakorpus contains recordings and transcriptions from Northern Sami areas.
Nordic Dialect Corpus is a speech corpus with Norwegian, Swedish, Danish, Icelandic and Faroese dialects.
NORINT Speech and NORINT Recited consists of spoken data elicited from adult international students learning Norwegian.
NORINT Text consists of texts written by adult international students learning Norwegian.

The two treebanks NDT Nynorsk and NDT Bokmål contain approximately 300,000 tokens each and are searchable in the search interface Glossa. You can search on morphological and syntactic categories, and get syntactic trees as results.

NoTa-Oslo: Norwegian Speech Corpus - the Oslo part
The Oslo Multilingual Corpus (OMC) is a collection of text corpora comprising original texts and translations from several languages.
Italian speech corpus with Italian native speakers living in Norway and non-native speakers living in Italy.
Finland-Swedish speech corpus with recordings and transcriptions from The Society of Swedish Literature in Finland.
The BigBrother Corpus is a speech corpus consisting of orthographic transcriptions linked to audio and video recordings from TVNorge's Big Brother broadcasts from 2001.

The Bokselskap Corpus contains texts from the website bokselskap.no.
ELENOR (Español Lengua Extranjera en Noruega/Spanish as a Foreign Language in Norway) is a database containing texts in Spanish written as course assignments by university students in Norway.
The ESV Corpus consists of transcriptions linked to audio files with recorded dialogues and stories from the book En bok om Estlands svenskar 3 B.
News texts from the Linguistic Data Consortium.

The LIA Treebank contains speech segments from LIA Norwegian - Corpus of historical dialect recordings. The segments are annotated with morphological and syntactic information.

The NDC treebank contains speech segments from the Norwegian part of the Nordic Dialect Corpus. The segments are annotated with morphological and syntactic information.